Breaking the trillion-dollar bottleneck.

Sailplane is the agentic platform for the AI Hardware Ecosystem. Sailplane agents learn from collaboration with human technicians and operators, optimizing for what is most important to you. Together we bring GPU compute online in hours, not weeks, and get better every time.

Why it matters

Capital is moving faster than the people who make it work.

Market need

Hardware is arriving faster than capacity.

Chips and power are easing. The constraint now is turning assembled infrastructure into AI capacity customers can actually use.

Pain points

Expertise does not travel.

A few specialists carry each rack through build, commissioning and production. At every handoff, much of what they learned is lost, and skilled operators are hard to hire and keep.

Our vision

Infrastructure that remembers.

Agents that learn alongside technicians and operators, and keep a verified record of every component, so each incident makes the next one cheaper.

LOST AT HANDOFFLOST AT HANDOFFLOST AT HANDOFF IF EXPERTISE CARRIED ACROSS PHASES DAY −1Manufacturing DAY 0Commissioning DAY 1Workload bring-up DAY 2Production
What each team knows about the unitWhat the fleet could know
Who we serve

The hardware moves forward. Now the expertise does too.

From the factory floor to the production fleet, Sailplane agents carry every rack’s full history forward, so your teams bring capacity online faster and keep it running.

01

OEMs & Manufacturers

Racks that arrive tested, tuned and ready to run.

Every new rack generation brings new thermal, cooling, interconnect and firmware failure modes, and your test engineers relearn them line by line. When a rack fails at the customer site, what you learned in the factory rarely travels with it.

  • Higher first-pass yield and faster validation, with fewer reruns
  • A complete, replayable history ships with every rack
  • Fewer returns, lighter field support, faster customer go-live
See how it works on the line
02

Neoclouds

Capacity live sooner. Interruptions down.

Your revenue starts when capacity is billable, not when it is financed or delivered. Every week a hall sits in bring-up is debt service with nothing to bill, and every interruption in production comes back as SLA credits.

  • Faster commissioning, from delivered rack to billable capacity
  • Faster fault isolation and repair, so fewer SLA credits
  • Readiness evidence your customers and lenders can audit
Talk to us about your next build
03

Hyperscalers

New generations in production sooner. Every fault fixed once.

You have sold capacity you have not stood up yet, and each accelerator generation arrives denser, liquid-cooled and with new ways to fail. At fleet scale, failure is routine, and the fix too often lives with one technician at one site.

  • Faster bring-up and burn-in for each new rack generation
  • Fleet agents that isolate faults, place workloads and cut repair time
  • Built to share failure signatures across sites and feed them back to your suppliers
Talk to us about fleet operations
04

Sovereign Clouds

Expert-grade bring-up and operations that stay inside your borders.

You need AI capacity that runs in-jurisdiction, often air-gapped, and the specialists who know this hardware are scarce everywhere. Flying in outside experts or sending telemetry out defeats the point.

  • Runs fully on-premises and air-gapped; nothing leaves your control
  • Agents learn only from what your own technicians and operators confirm
  • Built for firmware attestation and chain of custody on every component
Discuss a sovereign deployment
05

On-Prem Enterprise

Production AI on your own floor, without hiring a supercomputing team.

You bought GPUs to run AI on your own terms, inside your budget, security policy and existing tools. Then a small team has to commission and run a liquid-cooled cluster, and expensive hardware sits idle while they learn.

  • A guided path from purchase order to first production workload
  • Expert operating knowledge built in, not hired in
  • More useful work from the hardware you already own
Plan your path to production
Lifecycle

One memory from silicon to retirement.

Seven stages, one continuous record. Sailplane connects them so each stage starts with what the last one learned.

Platform

Sailplane is at the heart of the AI infrastructure ecosystem.

The next generation of AI datacenter infrastructure agents will read and write through the graph. Agent-native context for every component over its life: queryable, versioned, replayable, and the basis for evals and benchmarks.

DesignFabricationAssemblyManufacturingCommissioningProductionDecommissioning Sailplane Intelligence COMPONENTSTATEVALIDATIONDATADECISIONPATHSCYCLETIMESLIFETIMEHISTORY
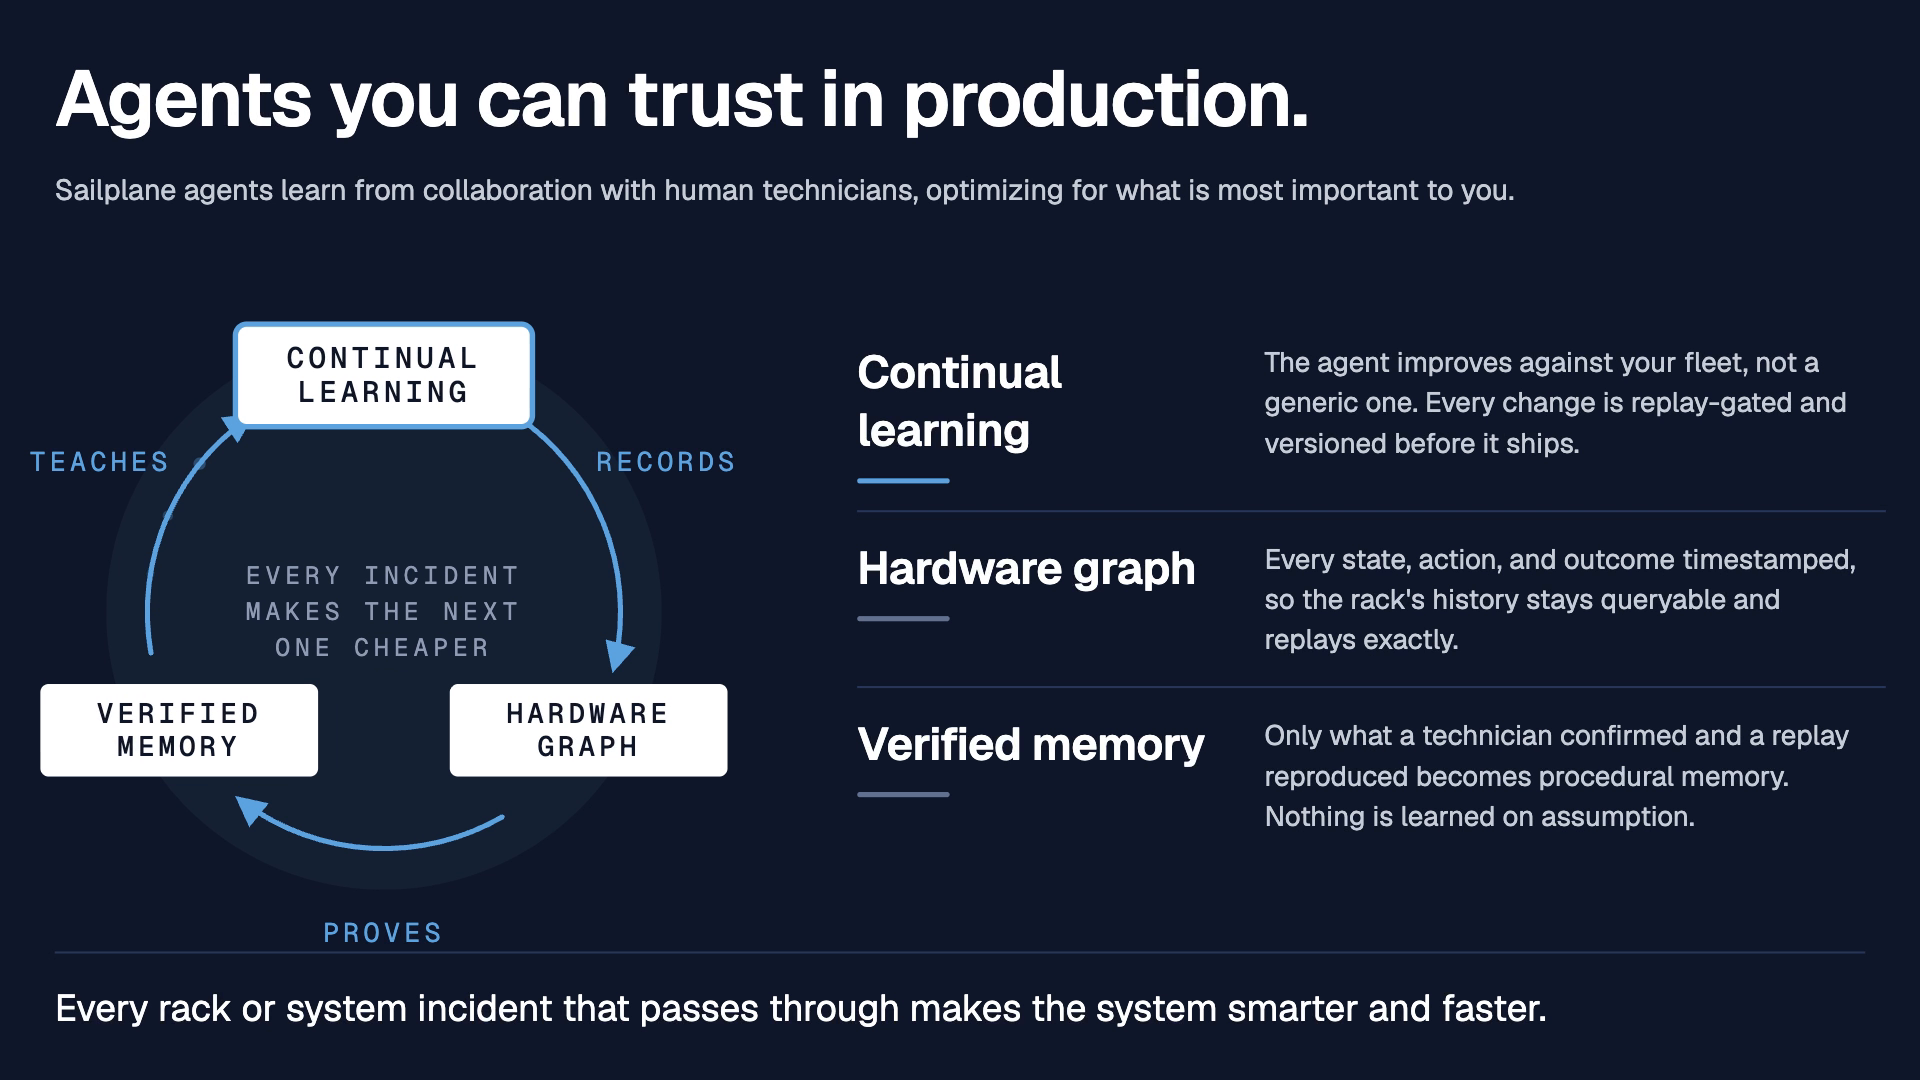
Agents you can trust in production. Sailplane agents learn from collaboration with human technicians, optimizing for what is most important to you. A flywheel: continual learning records into the hardware graph, which proves into verified memory, which teaches continual learning. Every rack or system incident that passes through makes the system smarter and faster.
Platform

Agents you can trust in production.

Sailplane agents learn from collaboration with human technicians and operators, optimizing for what is most important to you.

CONTINUALLEARNING VERIFIEDMEMORY HARDWAREGRAPH TEACHESRECORDS PROVES EVERY INCIDENTMAKES THE NEXTONE CHEAPER

Continual learning

The agent improves against your fleet, not a generic one. Every change is replay-gated and versioned before it ships.

Hardware graph

Every state, action, and outcome timestamped, so the rack’s history stays queryable and replays exactly.

Verified memory

Only what a technician and operator confirmed and a replay reproduced becomes procedural memory. Nothing is learned on assumption.

Every rack or system incident that passes through makes the system smarter and faster.

Results

Measured for AI Infrastructure Ecosystem

Engineered and optimized for KPIs on the factory floor

// signal: dwell_time

40%less dwell time per rack

Measured in A/B test.

// signal: test_runs

16%fewer test runs per rack

Fewer re-runs as technicians and operators get to root cause sooner.

// signal: cycle_time

28%faster validation cycles

Average per-rack reduction, replaying real NVL72 validation histories with each rack as its own control.

// signal: cycle_time

43%faster on the slowest 10% of racks

Biggest gains on the hardest racks, where escalations and rework pile up.

// signal: bay_capacity

~1.4×validation capacity from the same test bays

The same bays and crews validate more racks, based on modeled test-bay hours for a multi-rack order.

Results reflect specific customer environments, rack configurations and technician workflows; individual results vary.

Deployment

Runs where your infrastructure runs.

Air-gapped

Nothing leaves your facility. Agents and data stay inside the boundary.

On-prem

Deployed on your own hardware, inside your own network and controls.

Hybrid

Keep sensitive workloads local and extend to cloud where it makes sense.

Model optimized

Models tuned to your hardware and your workloads, sized for the system they run on.

Who we are

High talent density on a problem that matters.

Leaders who have run infrastructure software and hardware inside the world’s largest enterprises, alongside AI researchers and engineers. Earned scars, not adornment.

Sam Ramji

Sam Ramji

CEO

Microsoft, Google Cloud, Apigee

Francisco Uribe

Francisco Uribe

Chief AI Officer

Google Brain, Google Cloud AI, BlackLocus co-founder

The team has worked at
  • Google
  • Microsoft
  • AWS
  • Cisco
  • Apigee
  • Transmeta
  • U.S. Air Force
Working with us

Build AI infrastructure with Sailplane.

We work with teams building AI infrastructure from the ground up. Tell us what you are building and we will reply directly.

  1. 1
    Tell us what you are buildingYour hardware, your stage, and where expertise gets lost today.
  2. 2
    We scope a focused engagementOne site, one workflow, clear success criteria.
  3. 3
    Agents learn from your technicians and operatorsThen expand across the lifecycle, inside your environment.

Prefer email? Write to hello@sailplane.ai.